Benchmark scores depend on task coverage, protocol, and uncertainty. We connect MMLU, HELM, and MMMU to a reproducible evaluation checklist and a hypothetical Wilson-interval example.
摘要
一个分数只在明确的题目、提示、采样与评分协议下有含义。本文用知识测试、多维评估与多模态基准三条路径,讨论评估对象如何改变结论。我们进一步区分模型能力、系统能力与部署任务,并展示样本量如何影响不确定性;图中的统计例子使用假设样本,不能作为模型表现数据。[1][2][3]
1. MMLU 扩展了知识测试的覆盖
MMLU 包含 57 项学术与专业任务,让研究者能够观察模型在不同领域的差异。一个跨任务平均值可以帮助概括,却可能掩盖某个领域的失败。选择题表现也不能直接等同于开放式咨询、长任务执行或取得专业资质。基准的贡献是提供可比较的问题集合,而不是替代所有现实验证。[1]
2. HELM 说明准确率只是一个维度
HELM 把准确率、校准、鲁棒性、公平性、偏差、毒性与效率纳入评估框架,并说明哪些场景能够测量哪些维度。这种设计的重要之处在于把覆盖缺口与权衡公开。不能把不同含义、不同单位的指标随意加总为一个“综合智能分”,也不应把尚未测量的格子填成零分。[2]
3. 多模态题目改变了被测对象
MMMU 以跨学科的图文题目检验知识与推理,包含约 1.15 万道题、30 个学科。其价值不只是增大题量,而是引入图表、结构图等信息形式。若评估系统先通过另一个模型将图片转成文字,分数衡量的是整条处理链;若直接输入图片,则需要记录图像分辨率、裁剪与输入方式。[3]
4. 样本量决定结论能有多精确
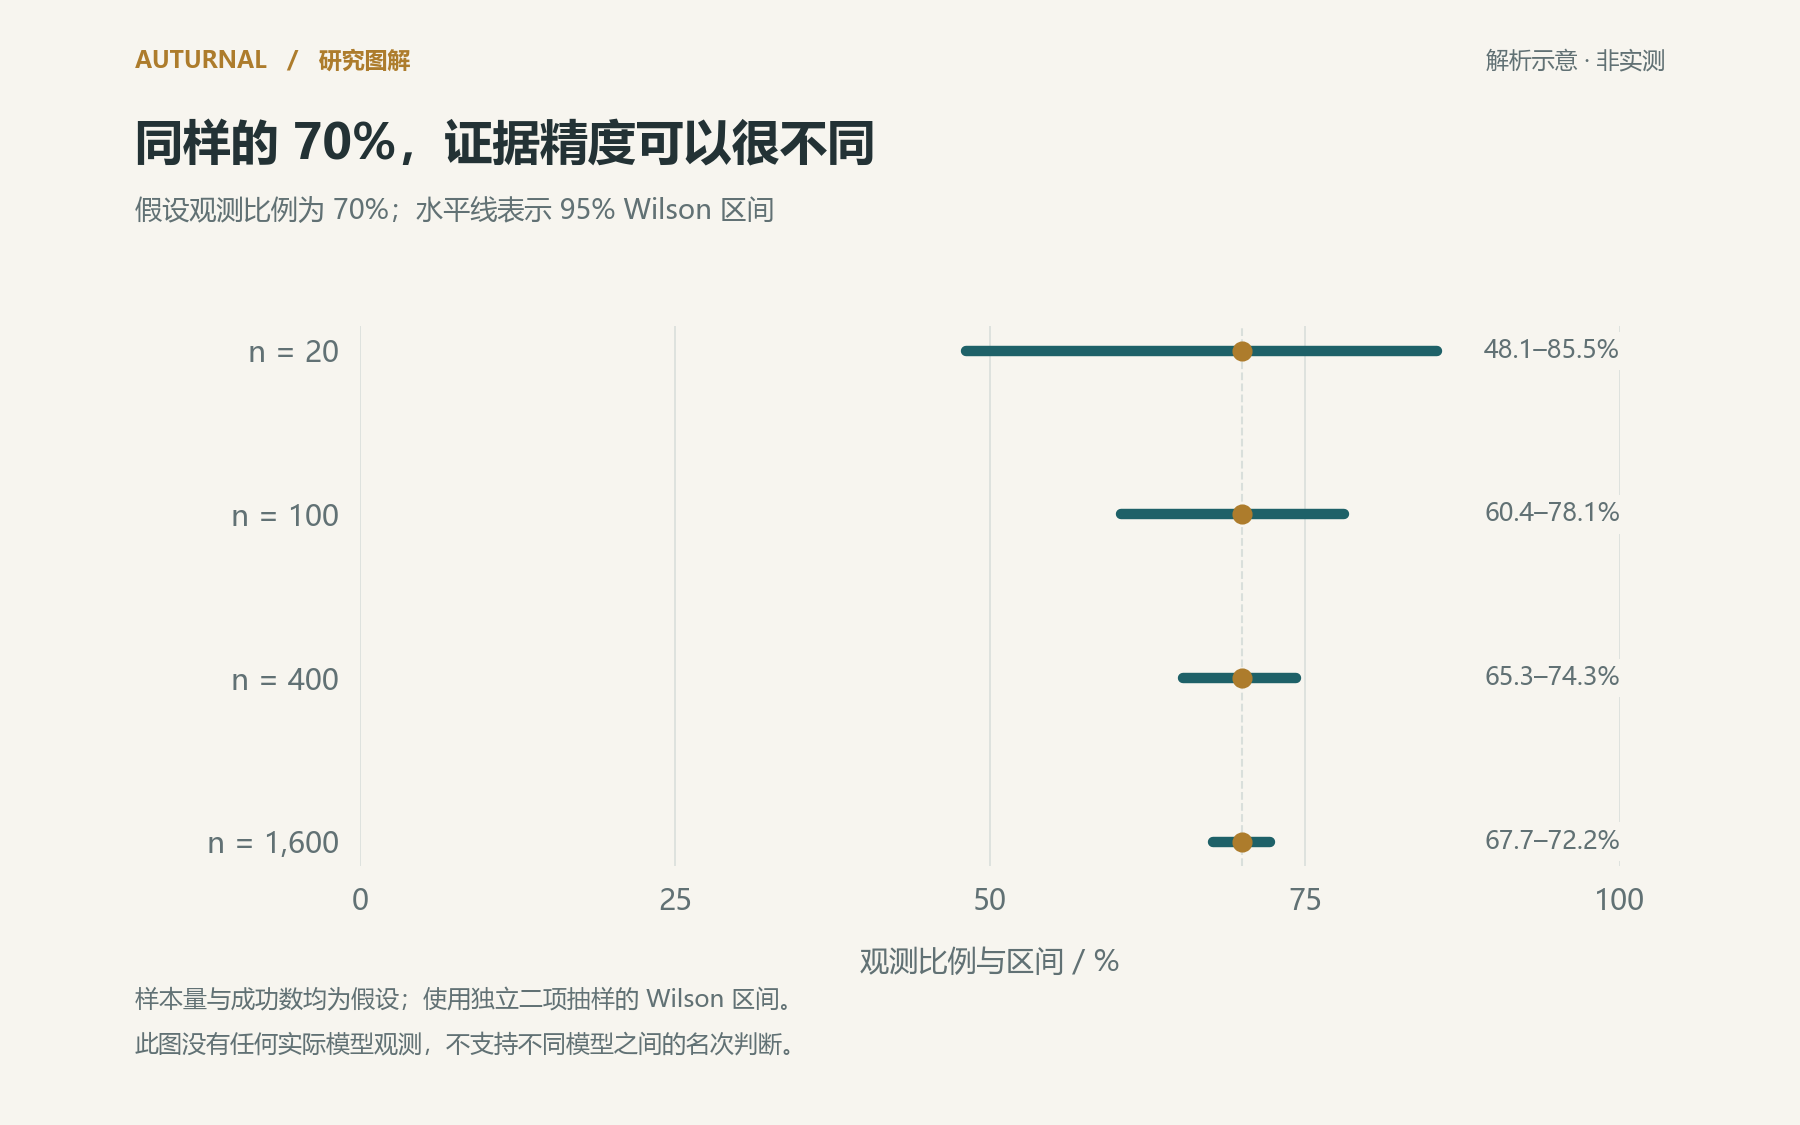
图 2 假设观测比例始终为 70%,分别构造 的二项样本,采用 95% Wilson 区间。它只用于解释样本量与区间宽度的关系,不来自任何模型。区间依赖独立二项观测假设;来自同一文档的多道题、重复用户或共享模板,可能使有效样本量小于题目总数。
5. 测试污染需要可追踪的时间线
如果评估题目或答案进入训练材料,基准可能同时测到记忆与泛化。本文建议记录训练可得数据的时间边界、评估集发布历史、去重方式与可能的近似重复。不能因为测试集没有出现在一个已知清单,就宣称完全无污染;也不能没有证据便指控某个具体模型泄漏数据。
6. 配对比较比两根柱子更有信息
同一批题目上比较两个模型,应保留逐题对错与任务类别,关注在哪些题目发生分歧。单独给出两个准确率和各自区间,不足以完整判断差异的不确定性。若题目具有类别层级,可使用相应分层或配对方法;若反复挑选最有利设置,应披露选择过程。本文未计算任何真实模型的显著性。
7. 复现记录应包含什么
至少保存题目版本、提示模板、few-shot 样例、解码参数、工具权限、模型标识、运行时间、失败与重试规则、评分器版本。开放权重与在线服务的可复现条件不同;服务可能在同一产品名下更新。记录协议可以帮助后续判断:变化来自模型、系统组件,还是评分条件。
平均值需要一个明确的权重
把每道题同权平均,与先算每个学科再同权平均,可能得到不同结果。前者让题量大的学科权重更高,后者强调领域之间平衡;两种做法都必须公开定义。如果目标用户只处理其中少数任务,还应报告与真实任务分布相匹配的结果。本文不指定一种适合所有用途的权重,也不把缺失学科推断为已覆盖。
后续实验可以如何设计
先冻结一个小而清晰的任务集与评分脚本,预先写下比较方法、失败计数和重试规则。对模型输出做配对记录,再按学科或任务类型分层观察。报告一个完整运行中的所有结果,而不是反复改提示后只选最好的一次。若要调整提示,应把开发集合与最终保留集合分开,让最终集合真正回答泛化问题。
局限与结论
本稿是一篇评估方法导读,不提供当前模型排名。MMLU、HELM 与 MMMU 的历史数字和框架不应被当成今天所有系统的现状。可信评估的关键是结论范围与观测范围一致,并保留足够细的证据,让别人能够检查覆盖、偏差与不确定性。
| 评估维度 | 应保存的证据 | 结论边界 |
|---|---|---|
| 任务覆盖 | 领域、题量与缺失项 | 平均值不覆盖全部用途 |
| 统计不确定性 | 逐题结果与抽样结构 | 单一区间不是万能证明 |
| 运行协议 | 提示、解码、工具和评分器 | 产品名不等于固定版本 |
Primary sources and claim mapping
- Hendrycks et al. · Measuring Massive Multitask Language UnderstandingOpen the primary source ↗Source date:2020-09-07;Checked:2026-10-15;Location:v3 abstract; 57-task benchmarkMMLU covers 57 academic and professional tasks; a task average is not general expert qualification.
- Liang et al. · Holistic Evaluation of Language ModelsOpen the primary source ↗Source date:2022-11-16;Checked:2026-10-15;Location:v2 abstract; seven dimensions and evaluation coverageHELM combines accuracy, calibration, robustness, fairness, bias, toxicity and efficiency where feasible; coverage and tradeoffs are explicit.
- Yue et al. · MMMU: A Massive Multi-discipline Multimodal Understanding and Reasoning Benchmark for Expert AGIOpen the primary source ↗Source date:2023-11-27;Checked:2026-10-15;Location:v4 abstract; dataset scopeMMMU combines 11.5K multimodal questions across 30 subjects. Historical model scores are not current performance guarantees.
Figure provenance, data and assumptions
[
  {
    "slug": "evaluation-beyond-leaderboards",
    "role": "conceptual-cover",
    "generator": "OpenAI built-in image_gen",
    "ai_generated": true,
    "alt": "白光经过棱镜和多个玻璃平面的多维评估概念插画。",
    "original_sha256": "2d73222de5a1e989ff37c7fc008842d4ba32725d984c1b1a1c1821058aa0779b",
    "prompt": "Premium scientific journal cover art, landscape 3:2, no text, numbers, logos, watermark or borders. A breathtaking editorial still-life with gallery-grade sculptural material, warm golden details, cinematic but natural illumination, believable shadows and highly tactile surfaces. Intelligent contemporary magazine art direction, refined color palette, memorable composition that reads at thumbnail size. Openly disclosed conceptual art, never an actual experiment or graph. Avoid flat diagrams, sci-fi brains, robot heads, computer chips, neon networks, cheap gradients and generic stock imagery. Topic: evaluation beyond a single leaderboard. A large impeccable optical glass prism stands among a few parallel translucent measurement planes on a matte ivory stone base. A soft shaft of white light passes through and separates into three restrained muted teal, amber, and coral light bands landing in different areas; NOT a full rainbow. Composition shows multiple perspectives and uncertainty, elegant light optics, immense negative space with subtle cool-gray backdrop, fine gold metal edges, museum still-life, pristine glass caustics, strong artistic focus. No charts, rulers or labels.",
    "files": [
      {
        "file": "assets/covers/evaluation-beyond-leaderboards.png",
        "width": 1280,
        "height": 853,
        "bytes": 1455614,
        "sha256": "032769eee5642cfe65cd45e846417dd5f198acecf7d67371f8d35e5299eb5cef",
        "url": "/guides/assets/v2-evaluation-beyond-leaderboards-032769eee564.png"
      },
      {
        "file": "assets/covers/evaluation-beyond-leaderboards-480.png",
        "width": 480,
        "height": 320,
        "bytes": 228332,
        "sha256": "2e05502949a1c814bc0eeb0f4325f2e73352d08c517fcc62ed47688ad92de7df",
        "url": "/guides/assets/v2-evaluation-beyond-leaderboards-480-2e05502949a1.png"
      }
    ],
    "url": "/guides/assets/v2-evaluation-beyond-leaderboards-032769eee564.png",
    "thumbnail_url": "/guides/assets/v2-evaluation-beyond-leaderboards-480-2e05502949a1.png"
  },
  {
    "slug": "evaluation-beyond-leaderboards",
    "role": "data-chart",
    "file": "assets/charts/evaluation-beyond-leaderboards.png",
    "width": 1800,
    "height": 1125,
    "sha256": "4762cdaadcc5ce85740fc5fe460c5d157bcc098eb4b33a46a4c5f9fe822c9295",
    "bytes": 115058,
    "alt": "图表:是假设比例 70%、独立二项样本 n=20/100/400/1600 的 95% Wilson 区间,非真实模型观测;不用于两个模型差异的显著性判断。",
    "data": {
      "kind": "analytical",
      "n": [
        20,
        100,
        400,
        1600
      ],
      "hypothetical_successes": [
        14,
        70,
        280,
        1120
      ],
      "observed_proportion": 0.7,
      "wilson_95_intervals": [
        [
          0.4810271816464765,
          0.8545227551323956
        ],
        [
          0.6041514536665332,
          0.7810511470506724
        ],
        [
          0.6533627542224784,
          0.7428323280438028
        ],
        [
          0.677088550988971,
          0.7219533845341277
        ]
      ],
      "assumptions": "independent binomial sampling; no actual model observations"
    },
    "data_source_sha256": "963323d4a7a0cad4aebd986f09a55251a7c21f68c757d21b76245a128675e13e",
    "ai_generated": true,
    "disclosure": "AI-assisted deterministic rendering of unchanged v1 data; not a new experiment.",
    "url": "/guides/assets/v2-evaluation-beyond-leaderboards-4762cdaadcc5.png"
  }
]
Author, versions and corrections
v3 adds five interface languages while retaining the original text, 29 sources and chart data. v1 and v2 remain available.
文献导读与方法分析;不是原创实验论文、正式期刊录用或专业资质认证。解析示例不代表本站或当前产品的实测表现。
View original v1 · Download the article, figures and source mappingView original v2