This review separates the architectural, algorithmic, and hardware contributions of attention models. Analytical memory examples illustrate scaling costs without claiming new model benchmarks.
摘要
Transformer 把序列位置之间的信息交换组织为注意力计算,为并行训练提供了不同于递归网络的路径。本文沿着“信息如何流动—计算如何增长—数据如何搬运”三条线索,分析原始注意力、稀疏注意力与 IO 优化的区别。核心判断是:架构允许并行、数学运算量和实际运行速度,应分别讨论,不能用一个吞吐数字替代。[1][2]
1. 先明确被改变的瓶颈
递归序列模型在一个样本内部,通常需要沿时间位置依次更新状态。原始 Transformer 用位置表示补充顺序信息,再让多个位置通过注意力交换内容。它缩短了远距离位置之间的信息路径,也增加了训练时跨位置并行的空间。不过,自回归解码仍需要依赖已经生成的词元;训练可以并行,不等于整段答案可以同时生成。[1]
2. Q、K、V 是计算角色
缩放点积注意力可以写成 :Q 与 K 形成匹配分数,softmax 将分数归一化,再对 V 加权。多头机制让不同投影子空间分别完成这一操作,再合并结果。这些名称描述向量在计算中的作用,并不意味着模型拥有可直接对应人类认知的“问题”“记忆”或“理解”模块。[1]
Código LaTeX
\operatorname{softmax}\!\left(\frac{QK^{\mathsf T}}{\sqrt{d_k}}\right)V3. 性能数字必须保留实验语境
原论文英文到德文 WMT 2014 实验报告,Transformer big 达到 28.4 BLEU。这个数字属于特定数据、分词、训练、解码与评分设置,不是现代通用语言模型的能力证明。本文不比较不同论文的英法分数:可访问版本的摘要、表格与正文存在不同写法,混用会制造并不存在的精确结论。[1]
4. 长上下文为什么昂贵
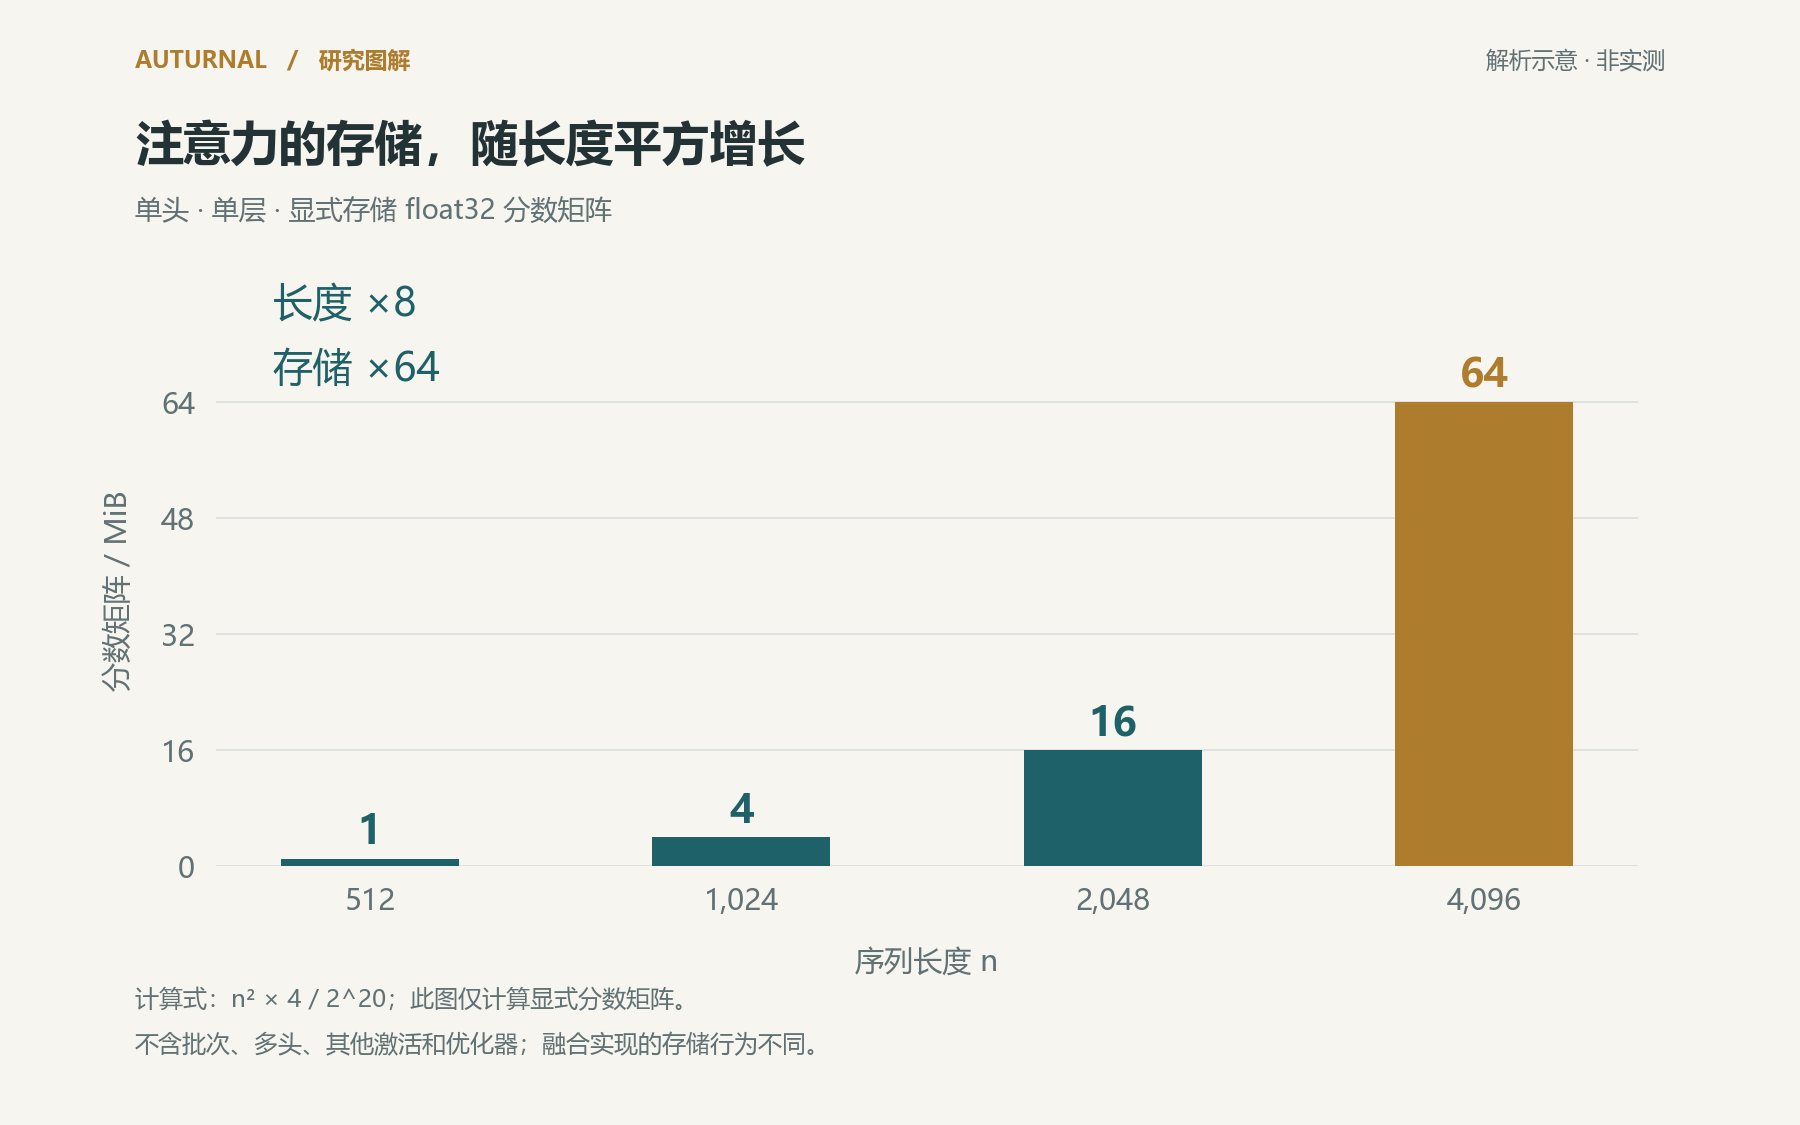
完整注意力在长度为 n 的序列上建立 配对关系。图 2 只计算“单层、单头、显式保存 float32 分数矩阵”的字节数:;长度翻倍,这一部分变为四倍。它不是完整训练显存估计,未计入梯度、激活、投影、批量、多头与优化器,也不适用于从不完整落盘分数矩阵的实现。[1][2]
5. 两种优化回答不同的问题
Longformer 改变哪些位置需要交互,用局部窗口与选择性的全局注意力处理长文档。FlashAttention 则围绕存储层级重排计算,借助分块与融合减少高带宽显存访问,保持其所定义的精确注意力。前者调整连接结构;后者优化同一计算的执行方式。不能把 IO 优化叫成消除了所有二次计算量。[3][2]
6. 可以复核的解析例子
取序列长度 512、1024、2048、4096,显式分数矩阵分别需要 1、4、16、64 MiB。计算使用二进制 MiB, 字节。图中的数字来自公式推算,不是 GPU 实测。若实现把分数分块留在片上存储,峰值占用会不同;因此应先看内核执行策略,再用这个例子解释趋势。[1][2]
7. 应如何比较一个“更快”的方案
本文建议分别报告训练样本长度、批量、精度、设备、预热、吞吐、首词元延迟和峰值显存,并在相同质量目标下比较。若一个方案截断了上下文,另一个保留全部输入,速度差包含任务变化;若一方使用融合内核,另一方使用朴素实现,差别也不能全部归因于架构。这是实验设计建议,并非本文的新实验结果。
一条容易忽略的计算边界
注意力分数的 项只描述位置之间的交互,投影与逐位置前馈仍有自己的计算成本。对于固定序列长度,增大隐藏维度会改变这些项的相对比重;对于固定维度,延长序列则会让位置配对更重要。因此,单凭“注意力是二次复杂度”不能预测整个模型每一部分的耗时占比。应先列出模型维度与输入,再解释实际剖析结果。
后续实验可以如何设计
可选择相同参数与序列,分别使用朴素完整注意力与已验证的融合实现,先检查输出与梯度在约定容差内一致,再测峰值显存、时间和吞吐。局部注意力应另设质量对照,因为它改变连接关系。预热、同步、精度与输入长度必须固定;首次编译和稳定运行应分别报告。该方案是待执行实验设计,本文没有生成对应测量记录。
局限与结论
这里讨论的是三篇基础研究揭示的机制,不能据此断言任一当前产品最快或最准确。注意力权重可以辅助观察信息交互,却不自动构成可信的因果解释。选择架构时,应把依赖范围、质量损失与设备约束同时列出;只有计算对象和测量口径一致,性能判断才有可比性。[1][3][2]
| 比较问题 | 应保留的条件 | 不能直接推出 |
|---|---|---|
| 架构并行性 | 训练或自回归解码阶段 | 整段输出同时生成 |
| 稀疏连接 | 窗口、全局词元与质量 | 精确保留全部交互 |
| IO 优化 | 内核、设备、精度与尺寸 | 消除全部二次运算 |
Fuentes primarias y afirmaciones
- Vaswani et al. · Attention Is All You NeedAbrir la fuente primaria ↗Fecha de la fuente:2017-06-12;Comprobado:2026-10-15;Ubicación:v7; sections 3-4; Table 2 (EN-DE only)Transformer uses scaled dot-product attention; full attention has quadratic pair complexity. EN-DE big model 28.4 BLEU; no cross-version EN-FR claim.
- Dao et al. · FlashAttention: Fast and Memory-Efficient Exact Attention with IO-AwarenessAbrir la fuente primaria ↗Fecha de la fuente:2022-05-27;Comprobado:2026-10-15;Ubicación:v1; sections 2-3Exact attention reorganizes memory IO using tiling; this is not a linear-time approximation of attention.
- Beltagy et al. · Longformer: The Long-Document TransformerAbrir la fuente primaria ↗Fecha de la fuente:2020-04-10;Comprobado:2026-10-15;Ubicación:v2 abstract and architecture descriptionLocal window attention combines with selected global attention; inference limits depend on architecture.
Procedencia de figuras, datos y supuestos
[
  {
    "slug": "transformer-attention",
    "role": "conceptual-cover",
    "generator": "OpenAI built-in image_gen",
    "ai_generated": true,
    "alt": "暖金细线连接深色玻璃平面的注意力主题概念插画。",
    "original_sha256": "9ae6e8d6e113d034f86d32e08dd248c561c3ee362928b63d8ea5df1ca2646a57",
    "prompt": "Create one exceptional premium science journal editorial COVER ART for an article about Transformer attention. Landscape 3:2 composition, edge-to-edge fine art, no border, NO TEXT, NO LETTERS, NO NUMBERS, NO LOGOS. A cinematic macro photograph of a real gallery-quality sculptural installation: many extremely thin brushed-gold threads span between three floating smoke-glass rectangular planes, some paths selectively illuminated, a beautiful woven fan of attention connections, precise engineering yet poetic. Make the sculpture fill the frame and read immediately at small thumbnail size. Deep ink-blue near-black background fading to slate, warm amber edge light, exquisite gold highlights, subtle ivory glass caustics, delicate dust, believable tactile material and physically grounded shadows, a striking asymmetrical diagonal composition with generous breathing room around the silhouette. Editorial art direction like a sophisticated contemporary scientific publication, museum photography, large-format lens, rich midtones, elegant restraint, immaculate craft. Not a chart, no scientific labels, not a literal experimental visualization. Avoid neon cyberpunk, generic glowing brain, humanoid robot, stock-tech chip imagery, flat infographic boxes, plastic CGI, rainbows, cheap gradients. This is an openly disclosed conceptual illustration of selective information connections.",
    "files": [
      {
        "file": "assets/covers/transformer-attention.png",
        "width": 1280,
        "height": 853,
        "bytes": 1559169,
        "sha256": "3d298d29aa96387052dcbe2558718f6711dd9b2d553ef98e778b9814686ad2be",
        "url": "/guides/assets/v2-transformer-attention-3d298d29aa96.png"
      },
      {
        "file": "assets/covers/transformer-attention-480.png",
        "width": 480,
        "height": 320,
        "bytes": 248011,
        "sha256": "b88782d3981eb0d0d6e2d00a76a0bc48c1fa4f66d23dc2b408b4b48619ef53bb",
        "url": "/guides/assets/v2-transformer-attention-480-b88782d3981e.png"
      }
    ],
    "url": "/guides/assets/v2-transformer-attention-3d298d29aa96.png",
    "thumbnail_url": "/guides/assets/v2-transformer-attention-480-b88782d3981e.png"
  },
  {
    "slug": "transformer-attention",
    "role": "data-chart",
    "file": "assets/charts/transformer-attention.png",
    "width": 1800,
    "height": 1125,
    "sha256": "13c38400f67a7c4c7adde30b5e03f64b3631e18c4975e3cb833b30254933ebd9",
    "bytes": 110862,
    "alt": "图表:为显式注意力分数矩阵的解析存储量;仅单头、单层、float32,非完整显存或速度实测。",
    "data": {
      "kind": "analytical",
      "length": [
        512,
        1024,
        2048,
        4096
      ],
      "MiB": [
        1.0,
        4.0,
        16.0,
        64.0
      ],
      "formula": "n*n*4/(2**20)",
      "excludes": "batch, heads, activations, gradients, optimizer; fused implementations differ"
    },
    "data_source_sha256": "963323d4a7a0cad4aebd986f09a55251a7c21f68c757d21b76245a128675e13e",
    "ai_generated": true,
    "disclosure": "AI-assisted deterministic rendering of unchanged v1 data; not a new experiment.",
    "url": "/guides/assets/v2-transformer-attention-13c38400f67a.png"
  }
]
Autoría, versiones y correcciones
v3 incorpora cinco idiomas de interfaz y conserva el texto original, 29 fuentes y los datos de los gráficos. v1 y v2 siguen disponibles.
文献导读与方法分析;不是原创实验论文、正式期刊录用或专业资质认证。解析示例不代表本站或当前产品的实测表现。
Ver el original v1 · Descargar artículo, figuras y referenciasVer el original v2