
Abstract
Synthetic data can reduce some annotation costs, but may also reproduce teacher errors, narrow coverage, or contaminate evaluation. This article treats generation, filtering, deduplication, and training as a process that jointly determines the effective data distribution, derives the probability that a rare event appears at least once after filtering, and discusses the limitations of this independent-sampling model. The accompanying plots are not model-degradation experiments; actual effects must be validated using independent real data and a fixed training budget.[1] Textbooks Are All You Need[2] Self-Instruct: Aligning Language Models with Self-Gener[3] Deduplicating Training Data Makes Language Models Bette
English abstract
Synthetic data pipelines are evaluated as sampling-and-selection systems. We distinguish correctness, coverage and dependence, derive rare-event retention under an explicit independent-sampling model, and describe contamination-safe controls. The coverage curves are analytical scenarios, not empirical model-collapse results. Real held-out data and provenance are required to assess a generated corpus.
1. Data volume is not effective information content
Generating a million texts does not mean obtaining a million independent learning signals. Similar prompts, the same teacher, repeated templates, and similar answers can produce strong correlations. Quality should also be defined separately in terms of factual correctness, task relevance, linguistic usability, and coverage of target populations; a single score may conceal different failures. Self-Instruct provides a concrete approach in which a model generates instructions that are then filtered, but every new setting still requires validation of its generation and filtering rules; a method's name cannot be treated as a quality guarantee.[2] Self-Instruct: Aligning Language Models with Self-Gener
2. Filters change both errors and coverage
Filtering may reduce obvious errors, but may also preferentially retain content that is common, easy to judge, or aligned with the teacher's preferences. If rare but correct samples are more likely to be falsely rejected, they will become even scarcer in subsequent training. Retention rates should be estimated separately for different categories, rather than reporting only the overall acceptance rate. If the filter and generator share blind spots, they may also endorse each other's errors. Human review requires stratified sampling by risk and the long tail, rather than examining only the batch most likely to pass.[1] Textbooks Are All You Need[2] Self-Instruct: Aligning Language Models with Self-Gener
3. Long-tail coverage can first be assessed probabilistically
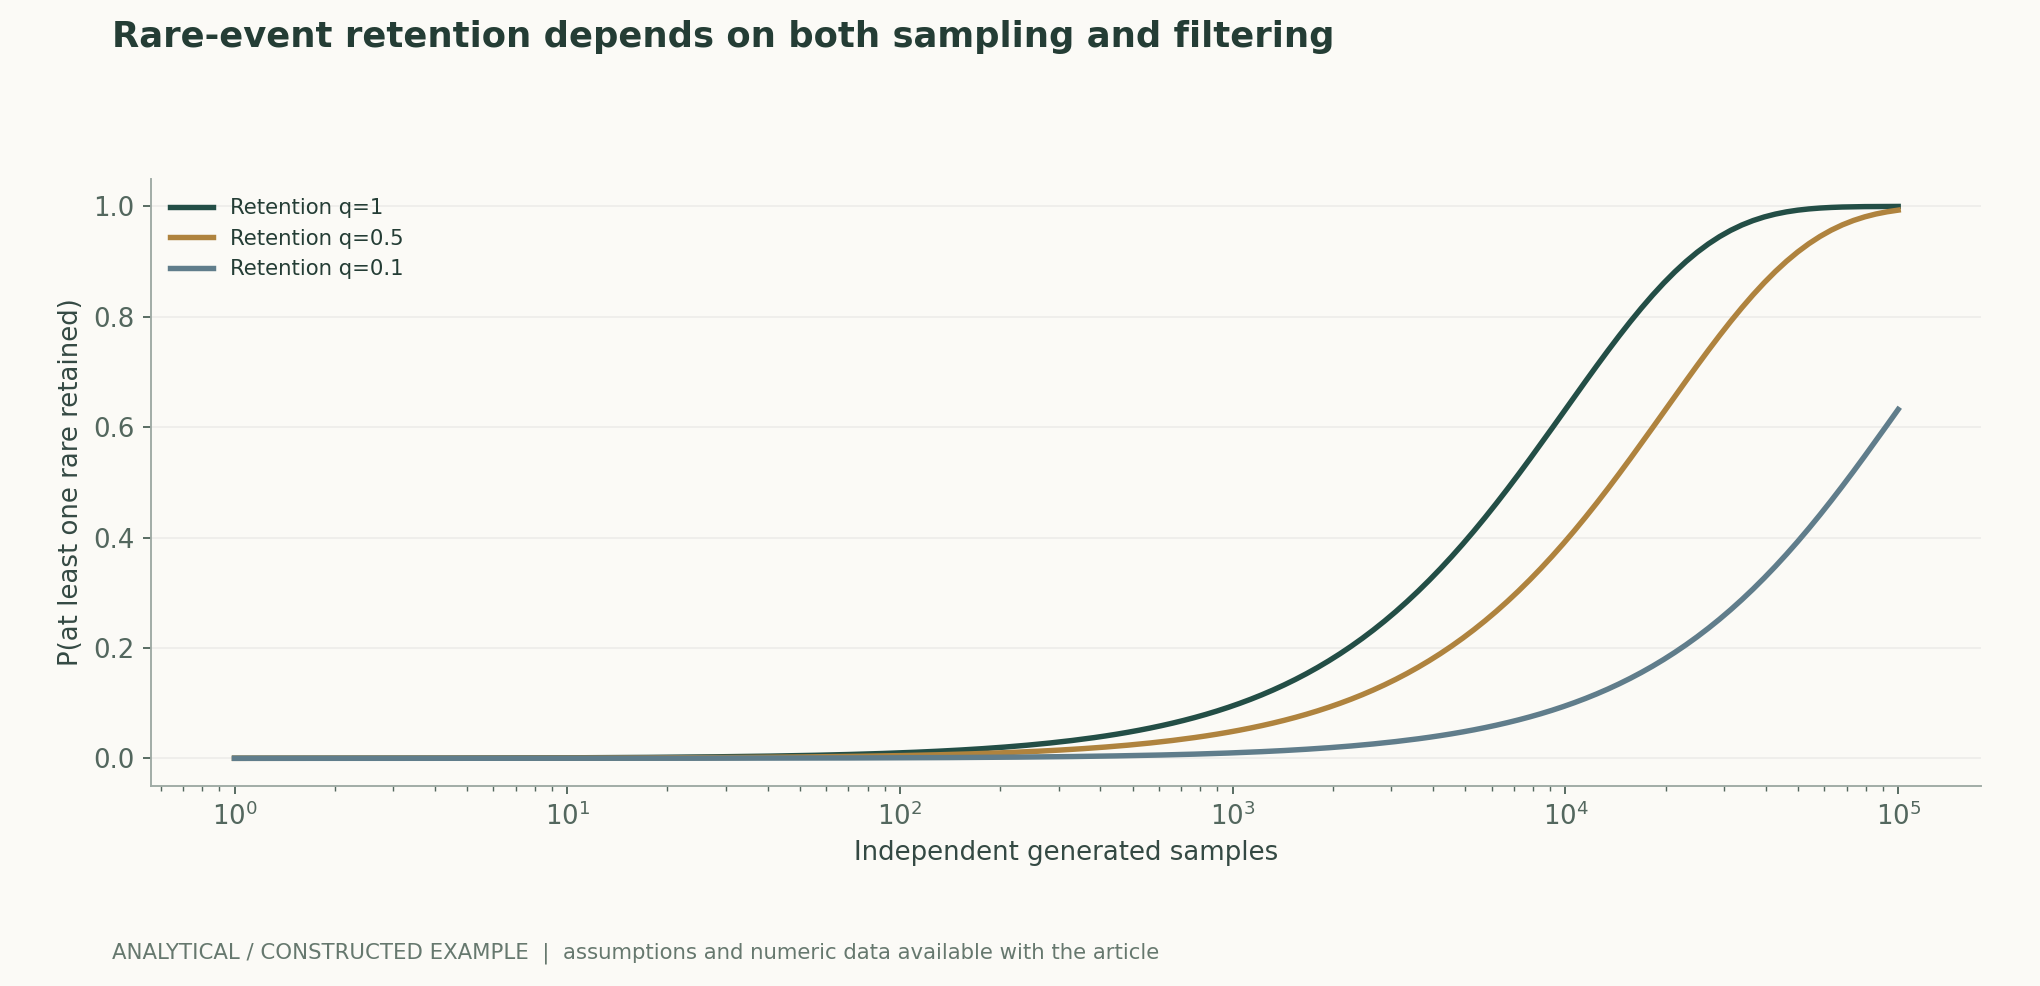
Suppose an event has an original probability p, its probability of being retained by filtering is q, and n generation trials are independent. The probability of retaining it at least once is then 1−(1−pq)^n. This formula clearly shows that more sampling and better long-tail retention can compensate for each other, but a single occurrence does not imply sufficient learning. When actual samples are correlated, the teacher's support is limited, or the event cannot be generated at all, the independence model will be overly optimistic. In the plot, p=0.0001, and q takes the values 1, 0.5, and 0.1, solely to explain this conditional relationship.[1] Textbooks Are All You Need
4. Recursive use of generated data requires retaining real-data anchors
Research on recursive training with generated data discusses the risks of losing distribution tails and accumulating errors; its conclusions depend on the model, data mixture, and training conditions, and cannot be reduced to a claim that all synthetic data are necessarily harmful. The key is to record each sample's provenance generation, the proportion of real data, and filtering and resampling rules, while tracking stratified quality on a fixed real test set. Continually generating with the current model and evaluating with similar models may create a closed loop without external ground truth.[1] Textbooks Are All You Need
5. Deduplication and contamination checks should operate at the family level
Rephrasings, translations, and teacher explanations of the same original question may span the training and test splits. Comparing only string hashes will miss semantic variants, while overly aggressive semantic filtering may mistakenly delete legitimate similar questions. Sample families, generation prompts, and source links should be preserved, related variants grouped before splitting, and similarity matches reviewed by humans. Research on training-data deduplication indicates that duplicated data affect memorization and the interpretation of evaluations; synthetic-data workflows should move these checks upstream.[3] Deduplicating Training Data Makes Language Models Bette[2] Self-Instruct: Aligning Language Models with Self-Gener
6. Acceptance requires matched budgets and independent evaluation on real data
When comparing synthetic-data approaches, hold the base model and total training tokens fixed, and vary the generation strategy, filter, and real/synthetic mixture ratio separately. Report generation costs, human-review costs, duplication rates, and coverage by category, rather than only the final training score. Testing should include real unseen inputs, rare cases, and sets of teacher errors. The coverage plot in this article is only a preliminary design calculation, not a certification of corpus quality, and does not establish that any mixture ratio is optimal.[1] Textbooks Are All You Need[2] Self-Instruct: Aligning Language Models with Self-Gener[3] Deduplicating Training Data Makes Language Models Bette
Core equations and derivations
(1) Assumes independent and identically distributed sampling and a constant retention rate; a single occurrence does not guarantee sufficient training.
LaTeX
P(\text{至少保留一次})=1-(1-pq)^n(2) In the example, p=10 raised to the negative 4 power; actual p and q must be estimated through stratified audits.
LaTeX
\mathbb E[N_{\mathrm{rare}}]=npq(3) a(x) is the probability that a sample is accepted, showing that the filter changes the entire distribution rather than merely removing errors.
LaTeX
P_{\mathrm{kept}}(x)\propto P_{\mathrm{gen}}(x)\,a(x)Methods and evidence workflow
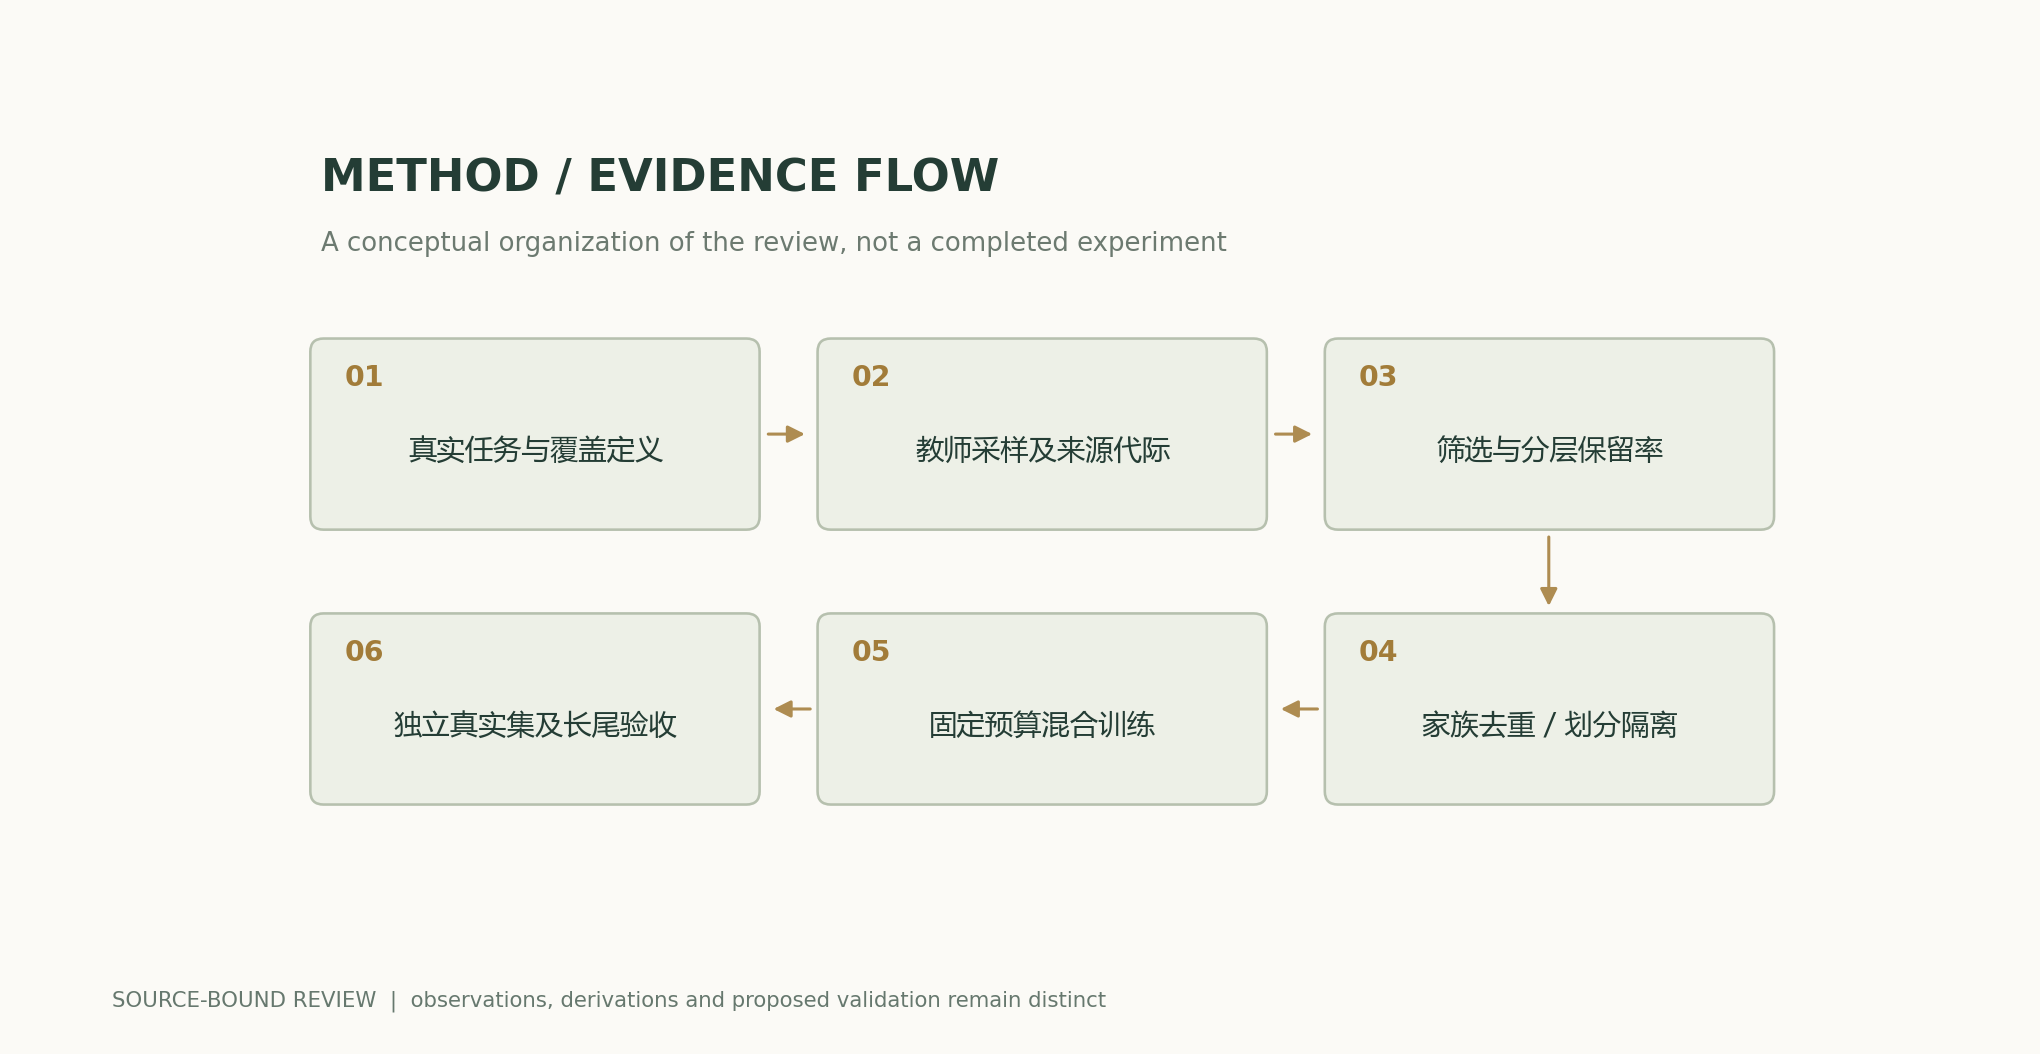
Analytical plots and numerical examples
Recomputable worked example
When n=10000, the probability of retention at least once is approximately 0.632 for q=1, and approximately 0.095 for q=0.1. Correlated generation or the teacher's lack of this pattern can make the independence model overly optimistic.
Comparison of methods
| Method or judgment | Controlled variables and measurements | Failure conditions and interpretation |
|---|---|---|
| Number of generated samples | Also report duplication, families, and coverage | More samples do not guarantee more independent information |
| Quality filtering | Measure precision and retention by category | The overall acceptance rate conceals false rejections in the long tail |
| Recursive training | Preserve generation information and real-data anchors | One cannot extrapolate that all synthetic data necessarily lead to degradation |
| Evaluation set | Maintain independent real sources and separation of families | A teacher evaluating its own generated samples may be circular |
Review and experimental plan
- Define target tasks and quality dimensions in advance, and fix an independent real test set.
- Record the generation model, prompts, sampling, provenance generation, and every filtering action.
- Split by family and perform exact and approximate deduplication; spot-check false positives and false negatives in semantic matching.
- Audit correctness, retention, and independence by common and rare categories.
- Hold training tokens and the base model fixed, and conduct ablations of filters and real/synthetic mixture ratios.
- Disclose generation, review, and training costs, and report the teacher failure set and long-tail quality.
Scope and limitations
- The coverage model assumes independent sampling.
- No new corpus-training or degradation experiments were conducted.
- A single long-tail occurrence does not guarantee learning.
- Filtering quality and coverage may conflict.
Mapping primary sources to claims
- Textbooks Are All You Need, , , , , , , , , , , , , , , , , , L12: View a PDF of the paper titled Textbooks Are All You Need, by Suriya Gunasekar and 18 other authors · 2023-06-20Abstract; 原文方法、理论和实验章节见作者原始论文链接
- Self-Instruct: Aligning Language Models with Self-Generated Instructions, , , , , , · 2022-12-20Abstract; 原文方法、理论和实验章节见作者原始论文链接
- Deduplicating Training Data Makes Language Models Better, , , , , , · 2021-07-14Abstract; 原文方法、理论和实验章节见作者原始论文链接
Citation and article export
BibTeXRISCSL JSONTXTArticle JSON
Author, version, and sources
An AI-assisted research review; Codex (AI) wrote the article and performed the analytical derivations based on the listed primary literature. This site has no record of independent peer review or original model experiments for this article.
Reader performance revision: previously read pages are also reused when a recent HEAD request returns 200 and the ETag matches. The body text, equations, sources, and scientific-figure data remain as in the previous version.
The conceptual cover is separate from the scientific illustrations; scientific figures are calculated from publicly available equations and explicit assumptions, and results from original papers are attributed to their sources.
Author, version, and correction history · /guides/synthetic-data-quality/v1/
Sources for the cover and scientific figures · Data, sources, and assumptions · Publication and version history
Source revision: 6251a250b27bb8b449f59b392f81abd355383770